 MyRecon OSINT
What Is OSINT? A Beginner's Guide to Open-Source Intelligence
Open-source intelligence, or OSINT, is the practice of collecting and analysing information that is freely and legally available to the public, then turning it into useful insight. No hacking, no special access, just publicly available data, gathered methodically.
A simple definition
The word "source" here refers to where the information comes from, and "open" means it is publicly accessible: websites, social media profiles, public records, news articles, domain registrations, maps, images, and more. OSINT is the discipline of finding the right pieces of that public data, verifying them, and connecting them into an answer to a specific question, for example, "does this person have a public LinkedIn?", "when was this website registered?", or "where is this server hosted?"
The concept is old, governments and journalists have practised it for decades using newspapers and public broadcasts, but the internet turned it into something almost anyone can do. The challenge today is rarely a lack of information; it is filtering, verifying, and making sense of an overwhelming amount of it.
What counts as an "open source"?
- The public web: websites, blogs, forums, and search engines.
- Social media: public profiles, posts, photos, and the connections between accounts.
- Technical records: domain WHOIS/RDAP data, DNS records, IP allocations, and TLS certificate logs.
- Public and government records: company registries, court filings, and property records where they are public.
- Media: images and videos, including the metadata and visual clues inside them.
- Data breaches: where checking public breach databases is legally permitted, to understand exposure.
The OSINT process
Good OSINT is a repeatable process, not random searching:
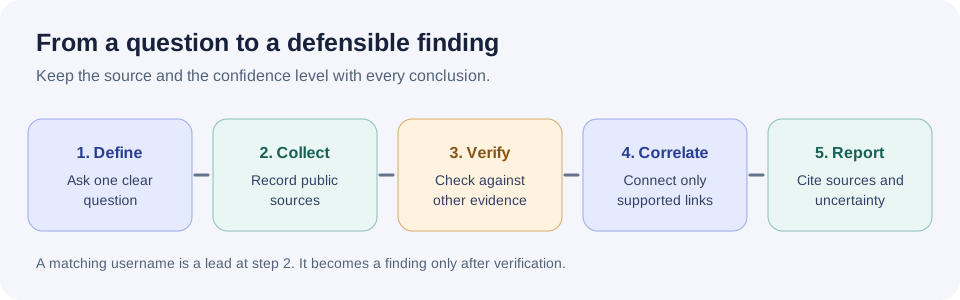
- Define the question. Vague goals produce vague results. Start with a specific, answerable question.
- Collect. Gather relevant data from open sources, starting with what you already know (a username, an email, a domain).
- Verify. Cross-check each finding against a second source. A single unconfirmed hit is a lead, not a fact.
- Correlate. Connect the pieces, the same handle on several sites, a website linked from a bio, to build a coherent picture.
- Report. Record your findings with their sources so the conclusion is defensible and repeatable.
Verification is everything. The most common OSINT mistake is treating a coincidence as a connection. Two people can share a username; a photo can be reused. Always confirm before you conclude.
Who uses OSINT, and why
OSINT is used far beyond intelligence agencies. Security teams use it to map their own organisation's exposure and investigate threats. Recruiters and fraud teams use it to verify identities. Journalists use it to corroborate stories with public evidence. Everyday people use it to audit their own digital footprint before a stranger does. The same techniques serve very different, legitimate goals.
Common OSINT techniques
Most practical OSINT falls into a few repeatable categories, each of which MyRecon supports:
- Username enumeration: finding where a handle exists across platforms. Read our guide on username OSINT.
- Email intelligence: provider analysis, linked accounts, and breach exposure.
- Domain and infrastructure analysis-WHOIS/RDAP, DNS records, and IP geolocation.
- Image analysis: reverse image search to trace where a photo appears.
The step most people skip: verification
Collection is the easy part of OSINT and the part every tutorial covers. Verification is the part that separates intelligence from a pile of links, and it is where beginners consistently go wrong.
The failure is simple to describe. You find a profile with the right username, it looks plausible, and you record it as belonging to your subject. But usernames are not identity. Popular handles are registered many times by unrelated people, distinctive ones get squatted across platforms by people reserving names, and impersonation accounts copy display names and photos deliberately.
The discipline is to ask what would have to be true for this to be wrong, before concluding it is right. Practically, that means grading your evidence:
- Strong: a cryptographic proof, a verified domain, or the person publicly linking the accounts themselves, ideally reciprocally, since anyone can link to a profile they do not own.
- Moderate: the same published email across both, a personal site listing both, consistent and specific biographical detail.
- Weak: matching display names, the same photo, similar interests, accounts created around the same time. Suggestive in combination, conclusive never.
Recording your confidence and the reason for it is not bureaucracy. It is what lets you revise a conclusion later instead of defending it, and it is the difference between a finding and a hunch.
Why tools disagree with each other
Run the same username through two OSINT tools and you will often get different answers. Both may be behaving honestly, and understanding why saves a lot of confusion.
Websites do not always tell you clearly whether an account exists. A great many return HTTP 200, "here is a page", for every possible username, because the page is built by JavaScript in your browser, or because it is a login wall, or because someone chose a branded "not found" screen over a proper 404. A tool reading only the status code will report an account for every handle it tries.
Platforms also respond differently depending on who is asking. Requests from datacentre address ranges are blocked far more aggressively than those from home or mobile connections, because that is where automated abuse comes from. The same check that a cloud-hosted scanner is refused for is frequently answered for a phone, so a tool running on your device and a tool running on a server will genuinely see different things.
The practical consequence: treat "found" as a lead, not a fact, and be suspicious of any tool that never says "I don't know". What a website's response actually tells you goes through this in detail with real measurements.
Building a repeatable method
Good OSINT is process, not cleverness. A workable loop:
- Write the question down first. "Does this company expose an admin login?" is answerable. "Find everything about this person" is not a question, it is an appetite, and it is how investigations turn into aimless collection.
- Decide what would answer it before you start looking, so you notice when you have enough and stop.
- Collect from the source, not from an aggregator repeating it. Aggregators copy errors faithfully.
- Record where each fact came from and when. Public information changes; a screenshot with a date is worth more than a claim.
- Look for disconfirming evidence before concluding. Two minutes spent trying to prove yourself wrong catches most mistakes.
- State confidence explicitly in whatever you produce.
The ethics and the law
Because OSINT uses public information, it is generally legal, but "legal" and "ethical" are not the same, and neither is unlimited. Collecting public data to review your own exposure or conduct authorized research is fine. Using the same data to stalk, harass, or dox someone is harmful and often illegal, and it can breach platform terms of service. Responsible OSINT means having a legitimate purpose, respecting privacy, and never weaponising what you find.
Getting started
The best way to learn OSINT is to practise on yourself. Search your own username, check your own email for breaches, and look up a domain you own. You will quickly see how much is public, and how the pieces connect. Try it with the MyRecon tools, then work through the rest of our guides, or take a single handle further with Deep Search.